From Scholar to Agent Engineer: My AWS AI & ML Scholars Journey

On October 8, 2026, I finished the Future AWS Agent Engineer Nanodegree. That same day, my third agent system passed all 120 points of its official test suite.

Most of my work has been computer vision on edge devices: cameras on plant floors, OpenVINO pipelines, Jetson boards in the field. Language models came into that work from the side, first as a way to summarise alerts and later as a way to reason over sensor data. In 2026 I wanted to learn properly how to build AI agents: systems that decide, call tools, keep state and recover from errors. The AWS AI & ML Scholars program gave me a structured way to do that.

How the program works

AWS AI & ML Scholars is run by AWS and Udacity in two phases. The Challenge phase is free and self-paced: it follows the AWS AI Practitioner learning plan and includes hands-on work with Amazon PartyRock and Amazon Bedrock. Up to 100,000 learners can take part. An assessment follows, and the top 4,500 learners receive a fully funded Udacity Nanodegree in one of three tracks. I chose the most technical one: Future AWS Agent Engineer.

Three projects, each harder than the last

  1. August: Customer Support Chatbot. One agent on an AgentCore Harness with three fixed routes and one database tool. The lesson: let the model suggest, and let code decide.
  2. September: AI Support Agent. One agent with six capabilities: Gateway tools, a Knowledge Base, Memory, Code Interpreter and Browser. The lesson: test the final reply, not just the tool output.
  3. October: NovaMart Multi-Agent RAG. A supervisor with four specialist agents, three knowledge bases searched at once, and shared state with version checks. The lesson: give each agent one job and keep their shared state consistent.

The main thing I learned: an agent isn't production-ready because it handles a good demo. It's ready when you can show what it did, why it did it, and that it does nothing when it shouldn't act.

Habits I'm keeping

  • Separate the model's suggestion from the decision. The model can choose a route. Plain code checks that the required fields are present before anything is written to the database.
  • Keep evidence. Each project shipped with recorded transcripts, screenshots, evaluation datasets and trace maps, so anyone can check the results.
  • Tear everything down. Every project ended with a check that no AWS resources were left running. It's easy to skip and expensive when you do.
  • Plan for production from the start. Even coursework should include notes on authentication, idempotent refunds and how long customer memory is kept.

The next three articles cover one project each, including the architecture, the mistakes and the evidence. If you're applying to the next round of the scholarship, I hope they help.
Read the full article Verify the certificate Credential spotlight About AWS AI & ML Scholars

Three Routes, One Guard: A Support Chatbot That Knows When Not to Write

The hardest part of a support chatbot is not writing good answers. It is not saving a half-finished bug report because the user said "yes" too early.

The brief sounds simple. A customer support bot for an online shop does three things. It collects bug reports and saves them. It answers questions about the shop. It hands everything else to a person. In practice each of those three routes can go wrong: the bot might save an incomplete ticket, make up a policy, or try to answer something it should hand off.

Three separate routes

I designed the conversation as three routes that never overlap:

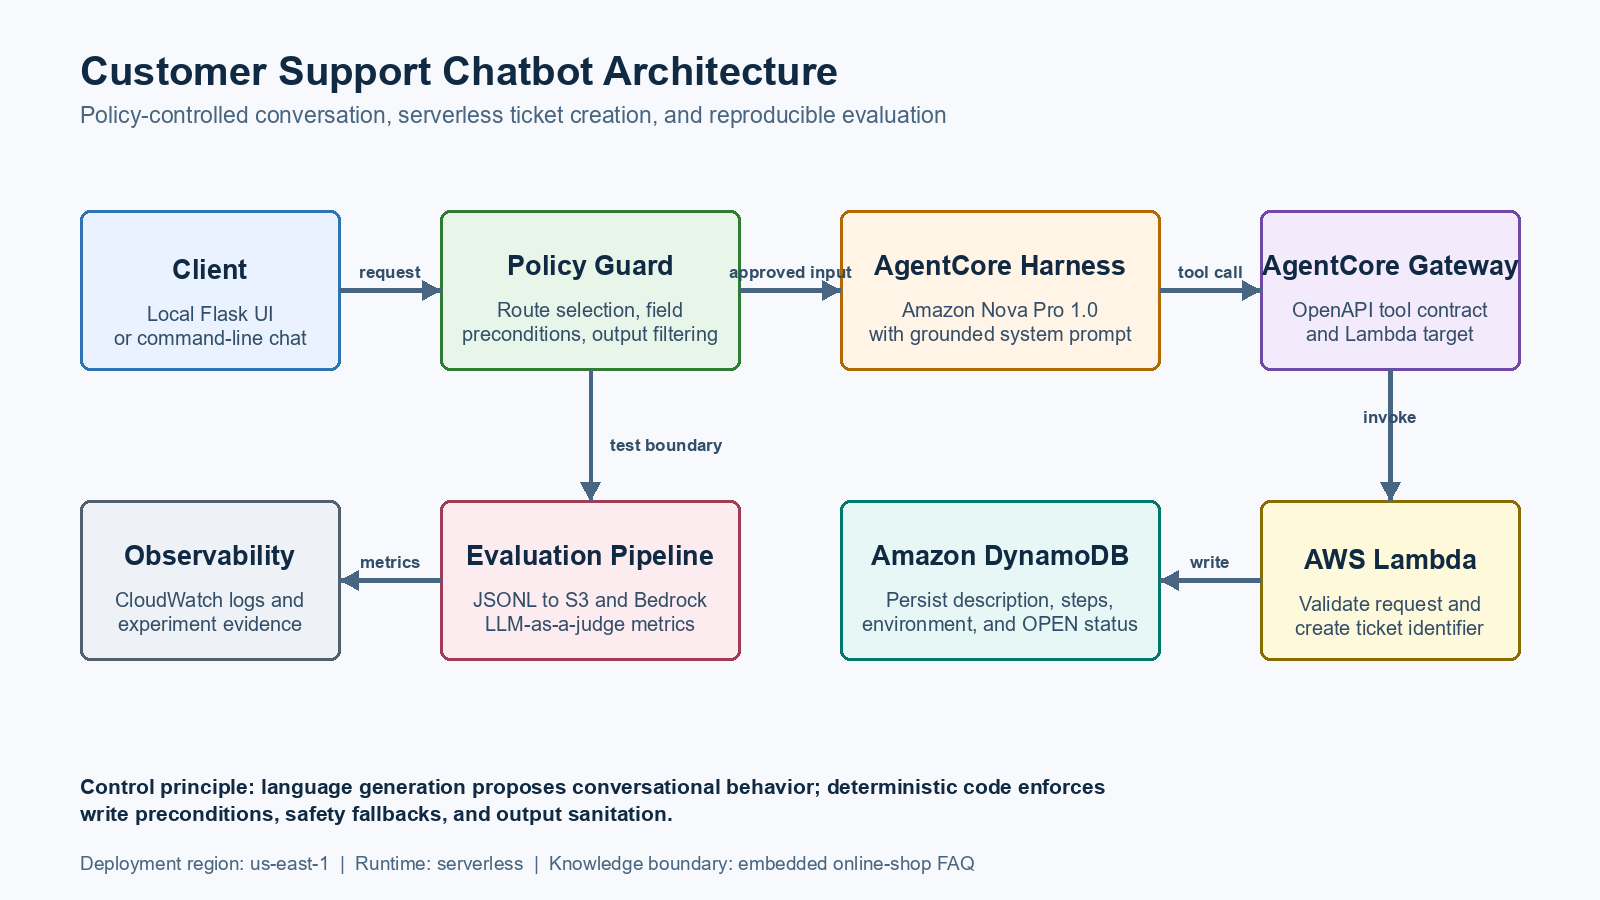
  • Bug report. Over several turns, collect a description, steps to reproduce and the environment. Then call create_bug_report through an AgentCore Gateway, which runs a Lambda function that saves the ticket to DynamoDB with status OPEN.
  • Shop FAQ. Answer only from the shop FAQ included in the prompt. No outside knowledge and no guessing.
  • Hand-off to a person. Anything the bot doesn't support goes to the support line, every time.
Architecture: client to policy guard to AgentCore Harness on Nova Pro to AgentCore Gateway to Lambda to DynamoDB, with an evaluation pipeline and CloudWatch observability
Fig. 1: Requests pass a policy guard before reaching the AgentCore Harness (Nova Pro 1.0). Tool calls go through the Gateway to Lambda and DynamoDB.

The model suggests, the code decides

The rule I followed: the model chooses what to say, and plain code checks anything that has side effects. A routing guard sits between the client and the harness. It checks preconditions before any database write, so a ticket can't be created until every required field is filled in. It also removes <thinking> tags from the streamed reply so the model's internal reasoning never reaches the customer.

Prompt-injection attempts ("ignore your instructions and…") are refused and sent to the hand-off route. The model can still be clever, but it can't be talked into writing to the database.

Showing why, without showing private reasoning

For the extra-credit part, I built a Flask web app with login and an explanation panel. For each reply it shows which route was chosen and where the answer came from. It doesn't expose the model's private reasoning. A support lead can see why the bot answered as it did without reading its internal notes.

Measuring it

I generated an evaluation dataset of ten test cases covering all three routes and the edge cases, and scored it with Amazon Bedrock, using a model to grade the answers:

CheckResult
Bedrock correctness (9 of 10 cases scored 1.0)0.95
Harmfulness0.00
Core pytest suite: Lambda, DynamoDB, prompt, Gateway, guard22/22
Flask UI suite: login, protected routes, explanation panel12/12
Evaluation dataset: valid schema, no leaked reasoning tags10/10
AWS resources left after teardown0

The one case below 1.0 was a mixed request: a bug report and an FAQ question in the same message. That's the right kind of failure to find. It shows exactly where the routing needs to split a message into two intents instead of picking one.

Helpfulness (0.53) and instruction following (0.50) scored lower, and I kept them in the report on purpose. A bot that asks for missing details or hands off correctly can still score low on "helpfulness" with a generic judge. Reporting all the scores is part of evaluating honestly.

Read the full article View on GitHub Project case study Next: Part 2

The Tool Was Right. The Answer Was Wrong.

My discount calculator returned $99. My agent told the customer $95. The tool's output was correct. Here's the four-dollar bug that changed how I test agents.

The second project was a support assistant that handles a whole customer conversation in one place. It runs as an async Strands app on AgentCore Runtime with Amazon Nova 2 Lite, and each capability has one clear job:

  • MCP Gateway: an API Gateway endpoint for order tracking and a Lambda function for refunds.
  • Bedrock Knowledge Base: catalog and policy facts stored in S3 and indexed in OpenSearch Serverless.
  • AgentCore Memory: hooks that bring back who the customer is and how they like to be answered.
  • Code Interpreter: arithmetic the model must not do in its head.
  • Browser: reading a live web page when the answer is only online.

The bug

Loyalty discounts have rules. Points are redeemed in 500-point blocks. Redemption can't exceed half the order value. The tier discount applies to what's left after points are redeemed. I put the whole calculation in Code Interpreter, using Python's Decimal with explicit rounding, so it would be correct every time.

The live test was a Gold member with 4,250 points and a $150 order. The tool returned:

{
  "points_redeemed": 4000,      // 8 blocks of 500 → $40.00
  "points_discount": 40.0,
  "tier_discount_pct": 10.0,
  "tier_discount": 11.0,        // 10% of the $110 balance
  "final_total": 99.0,
  "total_savings": 51.0,
  "remaining_points": 349,
  "calculation_mode": "code_interpreter"
}

The tool was right. But when the model summarised it for the customer, it applied the 10% Gold discount to the original $150 instead of the $110 balance: $150 − $40 − $15 = $95. The customer would have been promised a price the backend would never charge.

Checking the tool's output wasn't enough. The bug was in the step after the tool: the model rewriting a correct result in its own words.

The fix: the reply must match the tool

Reading the tool-call log showed exactly what happened. The fix was a check on every reply that keeps the calculator's JSON fields in the final answer, so the customer sees the numbers the tool produced, not the model's version of them. If Code Interpreter isn't available, the fallback gives a tier-only estimate and doesn't redeem any points, rather than guessing.

I applied the same idea to failures. Missing configuration gives a useful message, and Gateway errors give the customer recovery steps while the details go to the runtime logs.

Six live scenarios

ScenarioRecorded outcome
Order trackingSHIPPED · UPS
RefundAPPROVED · $139.99
Knowledge retrieval: Platinum tier benefits15% · same-day
Cross-session memory: name + preferencerecalled
Loyalty calculation$99.00 · 349 pts
Browser: live page titleretrieved

What production would need

Coursework uses sample data. Real customers would need more. Refunds need an authenticated identity: the Gateway should validate bearer tokens and confirm the customer owns the order. Refund processing should take an idempotency key so a retry can't pay out twice. Customer memory needs a retention period and a way to delete it. These controls should be tested alongside the normal support flows, not added later.

Read the full article View on GitHub Project case study Next: Part 3

Five Agents, One Customer: Multi-Agent RAG Without the Chaos

Adding more agents doesn't make a system smarter. It gives you more places for state to go wrong. NovaMart is how I kept five agents working together.

NovaMart is a support assistant for a fictional e-commerce shop. A single question like "Where's my order, and can I still return it?" needs order data, a refund decision and policy text. One agent with all those tools tends to mix the jobs up. So I split them into separate agents.

The agent graph

The system follows a supervisor-and-workers pattern on Amazon Bedrock AgentCore Runtime, built with the Strands Agents SDK:

  • OrchestratorAgent (Claude Haiku 4.5) has five tools: initialize_session and four route_to_* tools. It never answers the customer itself.
  • InventoryAgent looks up order and customer data (check_order_status, get_customer_tier, list_customer_orders) and makes no policy decisions.
  • PolicyAgent has a single tool, search_all_policies, which searches three knowledge bases at the same time.
  • RefundAgent checks eligibility, and starts a refund only when the customer explicitly asks for one.
  • CommunicationAgent always runs last. It reads the shared state and writes the reply.

All four workers run on Claude Sonnet 4.5. Routing rules are explicit: account questions never reach PolicyAgent, order-status questions check eligibility without starting a refund, and every request ends with CommunicationAgent.

Searching three knowledge bases at once

Returns, shipping and warranty policies each have their own Bedrock Knowledge Base backed by S3 Vectors. A question like "What's the warranty on electronics for Premium customers?" might need any of them. search_all_policies starts three retriever sub-agents in a ThreadPoolExecutor, runs them at the same time and combines their results with source citations. Total wait time is roughly the slowest search, not the sum of all three.

Shared state that can't be silently overwritten

Agents pass results through a shared WorkflowStateTable in DynamoDB, not only through prompts. Each record is keyed by session_id and stores a version number, timestamps, a TTL and every agent's result. Writes use a version check (optimistic locking):

read state            → version = n
worker produces result
conditional write     → only if version is still n
  ✓ commit             → store result, version = n + 1
  ✗ conflict           → reload state and retry

Two workers can't overwrite each other without noticing. When CommunicationAgent writes the reply, it reads a complete record that every worker has added to. AgentCore Memory adds seven-day session summaries on top, and a Bedrock Guardrail checks every request before it reaches the orchestrator.

Proving it works

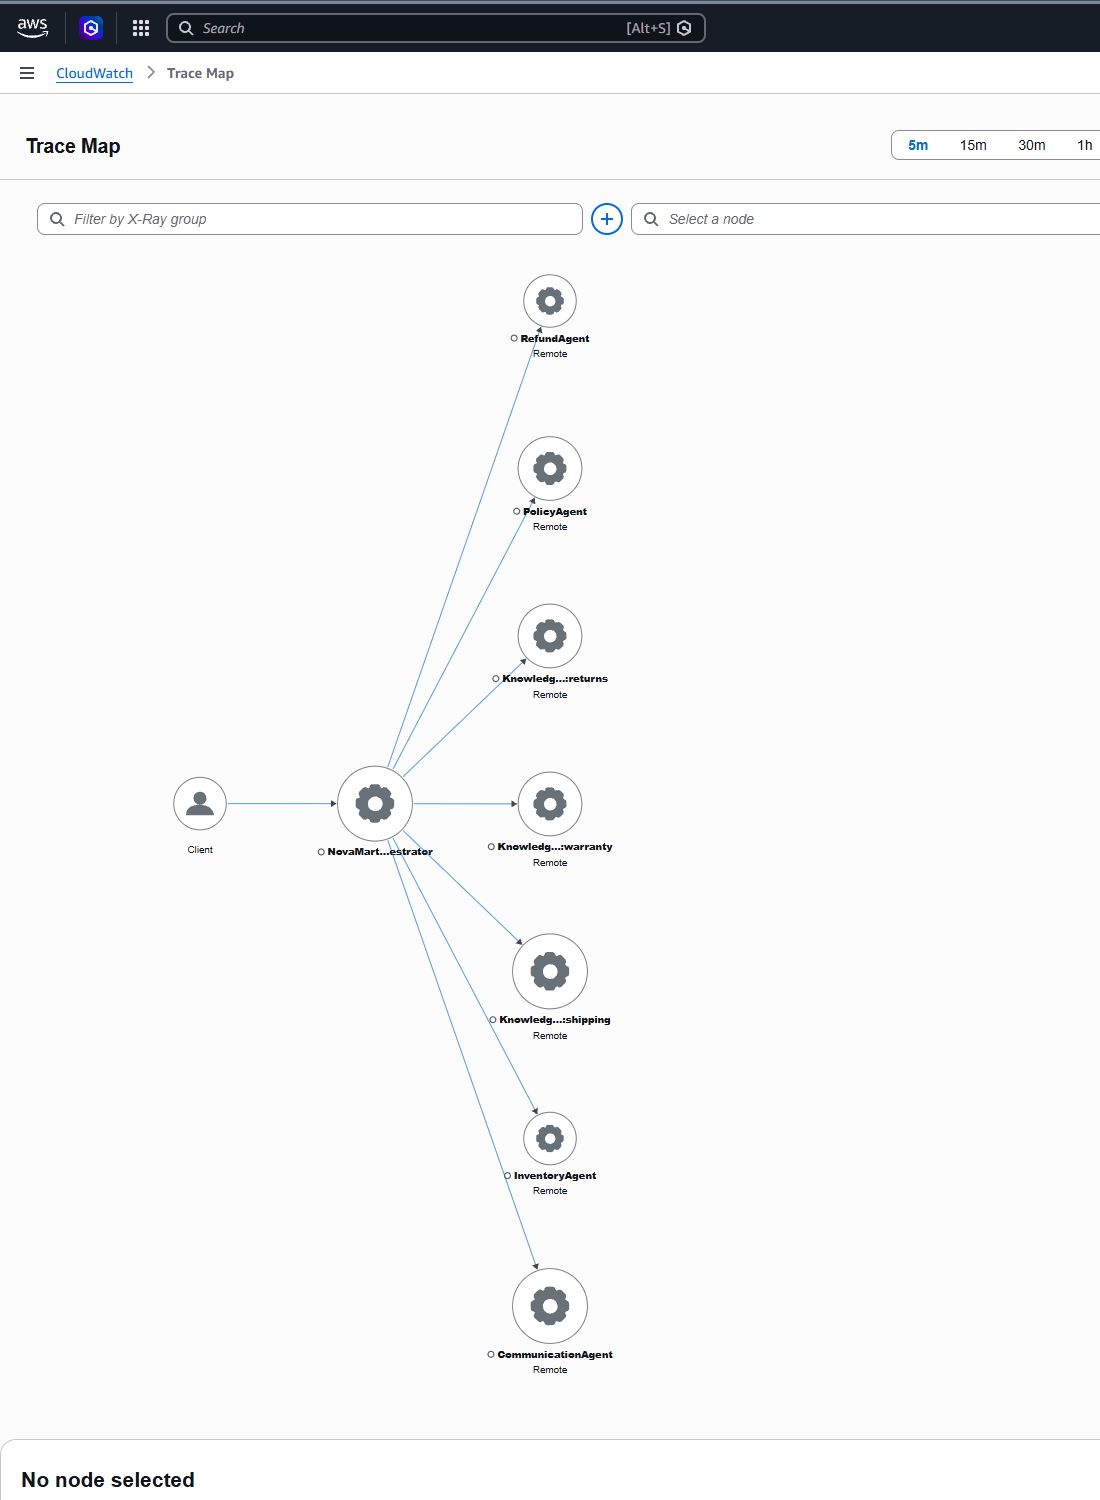
Observability counted toward the grade, and it should. With CloudWatch logging and X-Ray tracing at 100% sampling, the trace map after the final run showed the orchestrator connected to all four workers and all three knowledge bases, with no failed nodes.

CloudWatch X-Ray trace map: the client calls the NovaMart orchestrator, which connects to Refund, Policy, Inventory and Communication agents and the returns, warranty and shipping knowledge bases
Fig. 2: X-Ray trace map from the final three-scenario run. One orchestrator, four workers, three knowledge bases.

The official test suite, run on October 8, 2026 in the Udacity AWS sandbox:

Task: rubric areaScore
2: Multi-agent graph, tools, models and routing40/40
3: Guardrail and AgentCore Runtime20/20
4: AgentCore Memory15/15
5: Knowledge Bases and parallel retrieval25/25
6: CloudWatch and X-Ray observability20/20
Total120/120

What I'd tell someone building their first multi-agent system

  • Give each agent one job. If two agents could both answer a question, the routing rules aren't specific enough.
  • Put state somewhere you can inspect it. Prompts are a poor place to keep data. A versioned table can be audited.
  • Run independent steps in parallel. Parallel search is easy to add once retrieval is wrapped in its own tool.
  • Make tracing part of the design. If the trace map doesn't match your architecture diagram, one of them is wrong.
  • Automate the infrastructure. CloudFormation, CDK and GitHub Actions turned a one-off submission into something anyone can redeploy.
Read the full article View on GitHub Project case study Contact for collaboration

Industrial Anomaly Detection at the Edge

Industrial anomaly detection is not just a model problem. It is a latency, reliability, environment and trust problem wrapped around a model.

A plant-floor camera feed can reveal equipment anomalies, unsafe movement, missing PPE, blocked passages or near-miss events before they become incidents. The challenge is that the signal is noisy: lighting changes, dust, vibration, occlusion, glare and camera drift all create cases that look obvious to a human but confusing to a detector.

Why edge deployment matters

Sending every frame to the cloud is rarely the right first move. Industrial networks can be bandwidth constrained, cloud round-trips add latency, and safety alerts lose value when they arrive late. Edge inference keeps the detection loop close to the machine: frames are processed locally, alerts are generated near the source, and only compressed events or summaries need to travel upstream.

A practical pipeline

The pipeline I prefer starts with a production-shaped YOLO detector, then optimizes it for the target edge device using an inference runtime such as OpenVINO. A lightweight event layer sits after detection: it smooths short-lived false positives, applies zone rules, maps detections to equipment regions and emits events with timestamps, confidence and frame evidence.

This event layer is where many demos become systems. A single frame detection is not always an anomaly. A pattern across frames, a detection inside a restricted zone, or a sequence that violates a known operating state is much more useful to operators.

Designing for operators

The alert should say what happened, where it happened, how confident the system is and what evidence it used. That makes the system auditable. It also gives plant teams a way to tune thresholds without treating the model as magic.

The end goal is not to replace human supervision. It is to give operators a second set of tireless eyes that can watch every frame and surface the moments worth human attention.

Related project: Realtime Industrial Anomaly Detection Contact for collaboration

Multi-Modal LLM/RAG for Plant Intelligence

A detector can tell you that something changed. A plant-intelligence layer should help explain what changed, why it matters and what to check next.

Industrial data is naturally multi-modal. Cameras see motion and condition. Sensors record vibration, temperature, current, speed and pressure. Logs capture alarms, operator actions and maintenance history. Each stream is useful alone, but the real value appears when the streams are fused into context.

The role of RAG

Retrieval-augmented generation gives an LLM access to the plant's own documentation and event memory: standard operating procedures, maintenance notes, equipment manuals, prior incidents and alarm definitions. Instead of producing a generic explanation, the model can ground its response in the specific machine, zone and operating condition.

From detections to narratives

A useful architecture treats computer-vision detections and sensor anomalies as structured events. Each event includes timestamp, camera or sensor ID, equipment zone, confidence, class label and any linked frame evidence. The RAG layer then retrieves relevant context: what equipment lives in that zone, what the normal operating envelope looks like and what previous events resembled the current one.

The LLM's job is not to invent a diagnosis. Its job is to summarize evidence, show the retrieved basis, rank possible causes and suggest checks. For example: "Repeated rod misalignment detected near Zone B between 14:02 and 14:04. Similar historical events were associated with roller wear. Check camera feed B3, roller alignment and vibration trend."

Guardrails for the plant floor

Plant intelligence needs conservative behavior. Outputs should preserve uncertainty, cite retrieved evidence and avoid unsupported action commands. The best user experience is a compact alert first, with expandable evidence for engineers who need the full chain.

Done well, a multi-modal LLM/RAG system becomes a translation layer between raw machine signals and human operational judgment.

Related project: Multi-Modal Alert Summarization Contact for collaboration

Smart Weed Remover Robot: NVIDIA Jetson Nano with 3-DOF Parallel Robot

A weed-removal robot is a good mechatronics problem because perception and actuation have to agree in real space, not just on a screen.

The concept is straightforward: a mobile platform moves through crop rows, a camera identifies weeds, and a robotic mechanism removes the target plant without damaging the crop. The hard part is precision. A false positive can damage a crop. A delayed command can miss the weed. A weak mechanism can detect correctly and still fail physically.

System architecture

The NVIDIA Jetson Nano is a practical edge-compute choice for this class of prototype because it can run lightweight vision models close to the camera while still fitting the power and size constraints of a field robot. The vision stack detects weed candidates, estimates their image coordinates and projects them into the robot's working frame.

The actuation layer uses a 3-DOF parallel robot to position the end effector over the weed. A parallel mechanism is attractive here because it can offer stiffness and precise positioning inside a bounded workspace. That matters when the tool has to strike, cut, pull or disturb soil at a small target point.

Calibration is the quiet hero

The camera, mobile base and manipulator each have their own coordinate frame. The robot only works when those frames are calibrated well enough that a pixel-level detection turns into a reliable physical target. Camera calibration, height estimation, crop-row geometry and end-effector offset all become part of the intelligence pipeline.

Control loop

A robust loop looks like this: detect the weed, verify it across a few frames, estimate the target point, pause or slow the base, move the 3-DOF Delta mechanism into position, actuate, and then confirm that the target has changed. The confirmation step is important because agriculture is messy. Soil texture, leaf overlap and shadows can fool a one-shot system.

The engineering goal is a robot that uses chemicals less, handles weeds selectively and gives farmers a tool that is precise enough to be trusted. It is not just an AI project or a mechanical project. It is the integration that makes it useful.

Read the full article Related project: Robotics & Mechatronics Contact for collaboration

UltraEdge AIPC Studio: Building a Local Multimodal AI Lab on an AI PC

UltraEdge AIPC Studio is a local-first developer console for Intel AI PCs. It treats the AI PC as a real engineering workstation.

Most AI demos look great when everything is already installed, the model is warm, the camera behaves, the GPU is happy, and nobody asks where the data went.

Industrial AI is less forgiving.

In a real engineering workflow, the questions arrive fast:

Can this run locally? Which device is doing the work: CPU, GPU, or NPU? How much memory does the model need? What happens when the network is not available? Can I test audio, video, text, and code in one place? And the classic question: why did this work perfectly yesterday?

That is the practical problem I wanted to explore with UltraEdge AIPC Studio.

UltraEdge AIPC Studio is a local-first developer console for Intel AI PCs. It is built around a simple idea: an AI PC should not only run a chatbot. It should become a small local AI lab where engineers can prepare models, inspect hardware, run multimodal assistants, benchmark performance, and review privacy controls before pretending something is production-ready.

Project repository: UltraEdge AIPC Studio on GitHub

For the multimodal model direction, I also used OpenVINO’s Qwen2.5-Omni notebook as an important reference point: Omnimodal assistant with Qwen2.5-Omni and OpenVINO.

Why an AI PC Studio?

Usually, when testing a new model or workflow, you have to run multiple scripts, open different terminals, and guess what the hardware is actually doing.

I wanted a single unified interface that lets you:

1. Check hardware status (CPU/GPU/NPU usage) before running a model. 2. Manage models easily (download, optimize, set execution targets). 3. Chat with models across text, audio, and video modalities. 4. Execute code generated by the model locally inside a safe sandbox. 5. Benchmark model latency and throughput directly on the target hardware.

The Stack in Plain English

To build this, I used:

- Intel OpenVINO: The engine that makes models run fast across CPU, GPU, and NPU. - Python (FastAPI): The backend server managing models and hardware checks. - React (Vite): The frontend dashboard. - Qwen2.5-Omni: A powerful multimodal model that handles audio, vision, and text natively.

What We Will Do

The following steps will guide you through cloning the repository, installing the dependencies, starting the studio, and running your first multimodal inference locally on an AI PC.

Step 1: Clone the Project

First, get the code from GitHub.

Step 2: Install the Backend

You can use standard Python virtual environment or Conda to install the dependencies.

Step 3: Install the Frontend

Navigate to the frontend directory and install the Node packages via npm.

Step 4: Start the Application

Start the FastAPI backend, and in a new terminal, start the React (Vite) frontend.

Step 5: Use the Dashboard as the Control Room

Open your browser to `http://localhost:3000`. The first thing you'll see is the hardware dashboard showing real-time metrics for your Intel CPU, Arc GPU, and NPU.

Closing Thoughts

Industrial AI does not need more magical thinking.

It needs local tests, visible hardware context, practical model management, benchmark evidence, privacy-conscious defaults, and honest notes about what failed.

UltraEdge AIPC Studio is built in that spirit. It treats the AI PC as a real engineering workstation: a place to prepare models, test multimodal workflows, measure performance, and understand limits before making deployment claims.

That is the kind of AI PC workflow I want to see more often.

Read the full article View on GitHub Contact for collaboration